Data engineering · 2026
Retail Sales ETL Pipeline
Production-style batch ETL for a real retail dataset: validation, a star-schema warehouse, Airflow orchestration, and reruns that are safe by design.
- incremental re-runs by design
- idempotent
- schema warehouse model
- star
- lint + tests on every push
- CI
Architecture
Select a stage to explore it.
01 · Extract
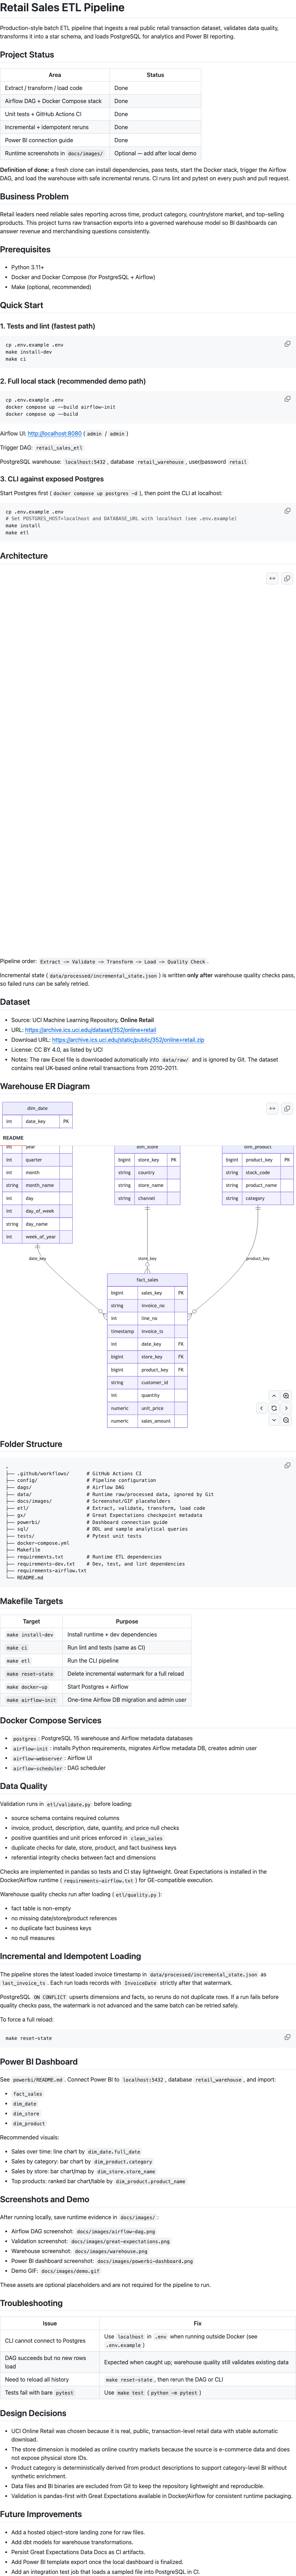
Ingests a real public retail transaction dataset — raw exports with the mess left in: cancelled orders, missing customers, inconsistent codes.
Visuals
01 · Problem
Retail leaders need reliable reporting across time, product category, and market — but raw transaction exports are inconsistent and unsafe to report on directly. The goal: turn them into a governed warehouse model that BI dashboards can trust.
02 · Solution
A batch ETL pipeline with an explicit definition of done: a fresh clone can install dependencies, pass tests, start the Docker stack, trigger the Airflow DAG, and load the warehouse — with incremental reruns that never double-count.
03 · Engineering decisions
Idempotence was treated as a requirement, not a nice-to-have: pipelines fail, and a pipeline you can't safely re-run is a pipeline you can't operate. Validation runs before load so data quality problems surface at the boundary. The star schema trades storage for query clarity — the right trade for a reporting warehouse.
04 · Results
A reproducible warehouse stack with CI running lint and pytest on every push, ready for Power BI on top. The pipeline patterns here — validation gates, incremental loads, safe retries — are the same ones the streaming pipeline later applied in real time.
05 · Lessons learned
Batch ETL is where pipeline discipline is learned: if reruns aren't safe and quality isn't checked at the boundary, everything downstream inherits the problem.